Statistics and machine learning formulas in PDF
The formulas of statistics and machine learning, from Bayes' theorem to attention and cross-entropy loss, are typeset with the notation papers use.
Bayes' theorem, the normal density, estimators and confidence intervals, covariance matrices, softmax, attention, cross-entropy loss and gradient descent. Toggle: math.
Markdown source
Markdown · 49 lines# Statistics and machine learning
## Probability
$ P(A \mid B) = \frac{P(B \mid A)\,P(A)}{P(B)} \qquad P(B) = \sum_{i} P(B \mid A_i)\,P(A_i) \qquad \mathbb{E}[X] = \sum_x x\,P(X = x) = \int_{-\infty}^{\infty} x\,f(x)\,\mathrm{d}x $
The normal distribution and its standardization:
$ f(x \mid \mu, \sigma^2) = \frac{1}{\sqrt{2\pi\sigma^2}} \exp\!\left( -\frac{(x - \mu)^2}{2\sigma^2} \right) \qquad Z = \frac{X - \mu}{\sigma} \sim \mathcal{N}(0, 1) $
$ \operatorname{Var}(X) = \mathbb{E}\left[(X - \mu)^2\right] = \mathbb{E}[X^2] - \mathbb{E}[X]^2 \qquad \operatorname{Cov}(X, Y) = \mathbb{E}\left[(X - \mu_X)(Y - \mu_Y)\right] $
## Estimation
Sample mean, sample variance and a 95 % confidence interval for the mean:
$ \bar{x} = \frac{1}{n} \sum_{i=1}^{n} x_i \qquad s^2 = \frac{1}{n - 1} \sum_{i=1}^{n} (x_i - \bar{x})^2 \qquad \bar{x} \pm t_{n-1,\,0.975} \, \frac{s}{\sqrt{n}} $
Maximum likelihood and ordinary least squares:
$ \hat{\theta}_{\mathrm{ML}} = \arg\max_{\theta} \prod_{i=1}^{n} f(x_i \mid \theta) = \arg\max_{\theta} \sum_{i=1}^{n} \log f(x_i \mid \theta) \qquad \hat{\boldsymbol{\beta}} = (\mathbf{X}^{\top}\mathbf{X})^{-1} \mathbf{X}^{\top} \mathbf{y} $
The covariance matrix of three variables, with the correlation coefficient:
$ \Sigma = \begin{pmatrix} \sigma_1^2 & \rho_{12}\sigma_1\sigma_2 & \rho_{13}\sigma_1\sigma_3 \\ \rho_{12}\sigma_1\sigma_2 & \sigma_2^2 & \rho_{23}\sigma_2\sigma_3 \\ \rho_{13}\sigma_1\sigma_3 & \rho_{23}\sigma_2\sigma_3 & \sigma_3^2 \end{pmatrix} \qquad \rho = \frac{\operatorname{Cov}(X, Y)}{\sigma_X \sigma_Y} $
## Information
$ H(X) = -\sum_{i} p_i \log_2 p_i \qquad D_{\mathrm{KL}}(P \parallel Q) = \sum_{x} P(x) \log \frac{P(x)}{Q(x)} \qquad I(X; Y) = H(X) - H(X \mid Y) $
## Machine learning
$ \operatorname{softmax}(\mathbf{z})_i = \frac{e^{z_i}}{\sum_{j=1}^{K} e^{z_j}} \qquad \sigma(x) = \frac{1}{1 + e^{-x}} \qquad \operatorname{ReLU}(x) = \max(0, x) $
Cross-entropy loss over $N$ examples and the gradient step with learning rate $\eta$:
$ \mathcal{L}(\theta) = -\frac{1}{N} \sum_{i=1}^{N} \sum_{k=1}^{K} y_{ik} \log \hat{y}_{ik} \qquad \theta_{t+1} = \theta_t - \eta \, \nabla_{\theta} \mathcal{L}(\theta_t) $
Adam, with bias-corrected moments:
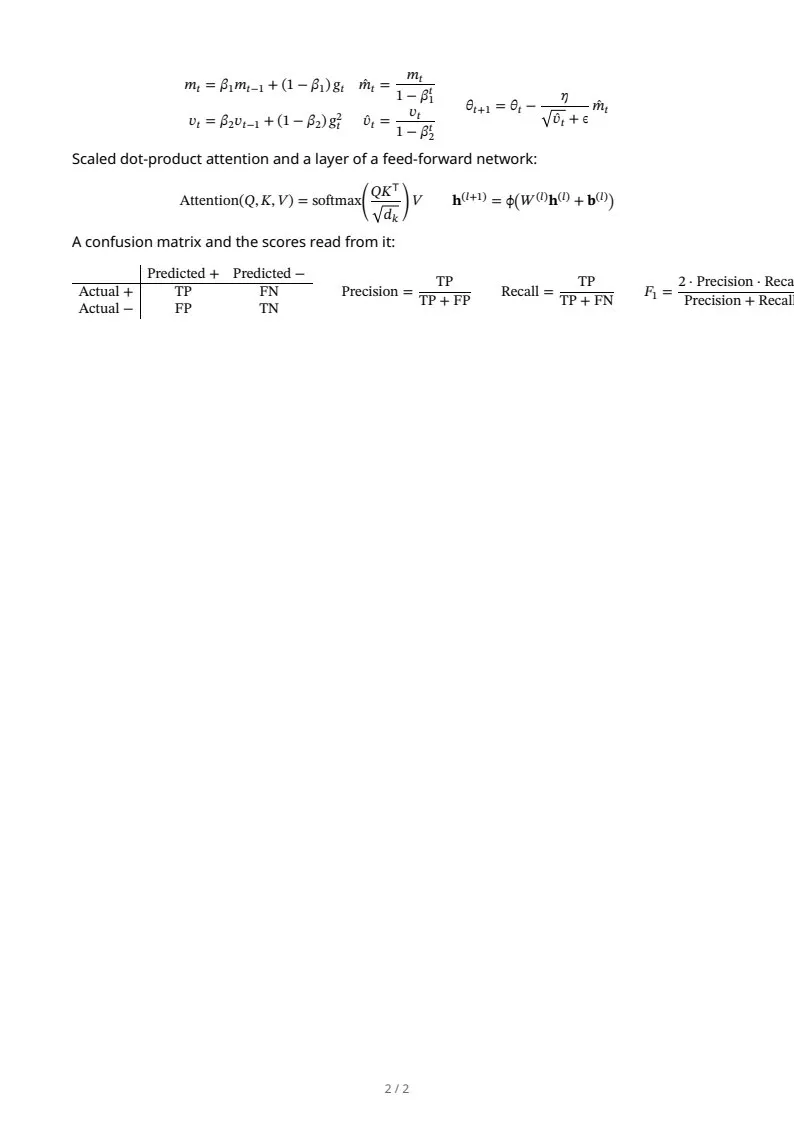
$ \begin{aligned} m_t &= \beta_1 m_{t-1} + (1 - \beta_1)\, g_t & \hat{m}_t &= \frac{m_t}{1 - \beta_1^t} \\ v_t &= \beta_2 v_{t-1} + (1 - \beta_2)\, g_t^2 & \hat{v}_t &= \frac{v_t}{1 - \beta_2^t} \end{aligned} \qquad \theta_{t+1} = \theta_t - \frac{\eta}{\sqrt{\hat{v}_t} + \epsilon}\, \hat{m}_t $
Scaled dot-product attention and a layer of a feed-forward network:
$ \operatorname{Attention}(Q, K, V) = \operatorname{softmax}\!\left( \frac{Q K^{\top}}{\sqrt{d_k}} \right) V \qquad \mathbf{h}^{(l+1)} = \phi\!\left( W^{(l)} \mathbf{h}^{(l)} + \mathbf{b}^{(l)} \right) $
A confusion matrix and the scores read from it:
$ \begin{array}{c|cc} & \text{Predicted } + & \text{Predicted } - \\ \hline \text{Actual } + & \mathrm{TP} & \mathrm{FN} \\ \text{Actual } - & \mathrm{FP} & \mathrm{TN} \end{array} \qquad \text{Precision} = \frac{\mathrm{TP}}{\mathrm{TP} + \mathrm{FP}} \qquad \text{Recall} = \frac{\mathrm{TP}}{\mathrm{TP} + \mathrm{FN}} \qquad F_1 = \frac{2 \cdot \text{Precision} \cdot \text{Recall}}{\text{Precision} + \text{Recall}} $
Rendered pages
PDF · 2 pages · 40 KB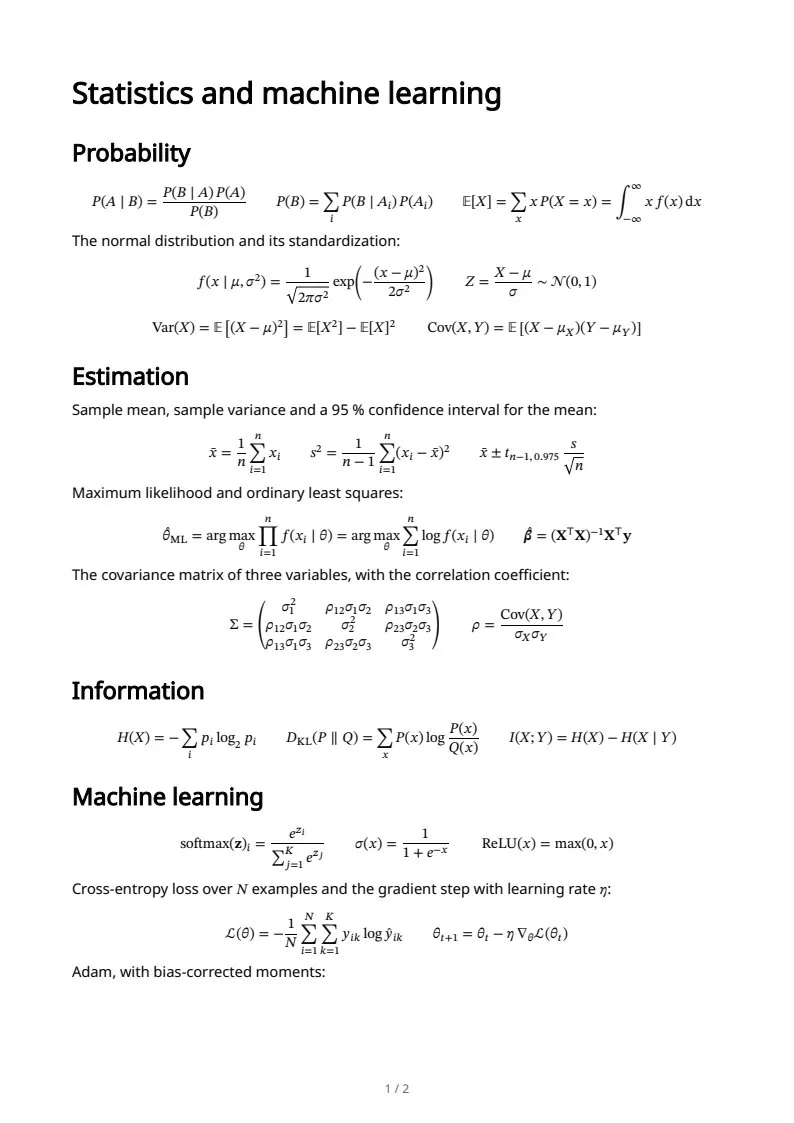
The sample documents describe invented organizations in several countries. All names and figures are illustrative.
LaTeX math in Markdown to PDF: every sampleIn the Markdown reference